Articles
Insights and updates from businesses and people across BONC Network.
Type
90 articles
Market Study
BONC Network Newsletter - September 2026 Week 5
Welcome to BONC Network What has happened in Global business in the last week of September 2026 - Let's uncover it. Do subscribe for regular overview by BONC Network editorial team on Global Business and financial market weekly.
#boncnetwork#newsletter#globalbusiness
Analysis
Generative AI for Drug Discovery and Biomolecules: Opportunities, Challenges and the Future of Healthcare
Making drugs is a very hard and slow job. It takes a lot of research, testing and checking to make sure things work. Now Generative AI is coming up as a tool that might help researchers work faster. Of just looking at old biological data Generative AI can learn patterns from molecular and biological datasets to find new ideas. One big way to use Generative AI in drug discovery is to look for drug molecules. AI models can study how molecules are built and how they act. Then Generative AI can suggest molecular candidates that might work well. This helps researchers narrow down the list of things they need to test on in drug development. Generative AI can also help us understand things like proteins and how they talk to each other. By mixing molecular structures, biological datasets and scientific papers researchers can see links that are hard to find with old methods. Multimodal AI might be very helpful here because biological problems usually use different kinds of information at once. Large Language Models are also a deal for scientific research. Large Language Models can help researchers find and summarize papers pull out important facts and organize what they find. If we use Large Language Models with systems that can look up files the AI can give answers based on actual scientific documents instead of just guessing. We must remember that Generative AI is not a replacement, for real scientists or lab tests. We still have to check every molecule or prediction that Generative AI makes. If the training data is bad or the model is biased the results will be bad too. A prediction might look great on a computer. It might fail in a real biological setting. This is why we need to use AI in healthcare and life sciences. We must check if these systems are reliable, clear and fair. Human experts need to be the ones who look at what the AI says and make the scientific calls. I truly believe the best way to use Generative AI in drug discovery is to have AI and human experts work together. Generative AI can scan through amounts of data and come up with new ideas very fast. Then scientists can use their knowledge to test those ideas in a lab. Using Generative AI Machine Learning, biological data, molecular modeling and human brains together could change the future of making medicine.. These systems will only work if we build them in a responsible way and test them properly.
#GenerativeAI#ArtificialIntelligence#DrugDiscovery
Case Study
Generative AI Shaping Industry 2026
Artificial Intelligence (AI) is no longer just a research concept; it is actively transforming industries worldwide. From healthcare and logistics to retail and defense, AI adoption is reshaping workflows, decision‑making, and customer experiences. Healthcare: Generative AI is accelerating drug discovery and biomolecule design, reducing R&D timelines. Automotive & Logistics: Computer vision enables autonomous systems, improving safety and efficiency. Government & Private Sector: AI enhances governance, predictive analytics, and citizen services, while businesses leverage hyper‑personalization for customer engagement. Tech & Cloud: MLOps and continuous model governance ensure scalable, reliable AI deployments. Ethics: Responsible AI governance is critical to address algorithmic bias and ensure fairness. Conclusion: AI is not just a coding tool—it is a driver of global market impact. Organizations that embrace AI responsibly will gain competitive advantage, while those ignoring it risk falling behind.
#GenerativeAI
Case Study
RAG Made LLMs Smarter. But Did We Make Them Safer?
Everyone is talking about RAG. And for good reason, it solved a real problem. LLMs are powerful, but they only know what they were trained on. RAG gives them access to your documents, your databases, your private knowledge. But here's the question nobody asked loudly enough: What happens to sensitive data before it reaches the vector database? Let me make this concrete. A company wants an internal AI assistant. Employees upload HR documents, customer contracts, medical records. The RAG pipeline chunks them, generates embeddings, and stores everything in a vector database. The assistant works beautifully. But now you have a new problem — one you didn't plan for. You've just created a searchable, queryable store of some of the most sensitive data in your organization. And the LLM sitting in front of it will happily retrieve and surface any of it. That's not a model problem. That's an architecture problem. That question is what led me to build LexiRedact. LexiRedact is a privacy-preserving middleware layer that sits between your application and your vector database. Before any content is embedded and stored, it: Detects PII using Microsoft Presidio (names, emails, phone numbers, medical identifiers, and more). Redacts or pseudonymizes sensitive entities. Generates embeddings from the sanitized content only. Stores the privacy-preserving version in ChromaDB. The key design decision I obsessed over wasn't detection accuracy. It was this: Privacy that destroys retrieval quality is not a solution. It's a different problem. So LexiRedact is built around a dual-pipeline approach: one path that prioritizes privacy, one that balances privacy with retrieval utility because the right tradeoff depends on what the data is and how it will be used. What the numbers look like: PII Detection F1 Score: 82.5% Sensitive data reaching the vector store: reduced by 78.9% Stack: Presidio · ChromaDB · Redis · FastEmbed · FastAPI Published as an open-source Python package: pip install lexiredact What building this actually taught me Most AI engineering conversations are about model selection, embedding quality, and retrieval strategies. Those are important. But production AI systems have a different layer of hard problems: What data are you actually storing, and should you be storing it? Who can retrieve what, and under what conditions? If your vector database is breached, what is exposed? How do you audit what your RAG system retrieved and why? These aren't model problems. They're system design and data governance problems. And they don't get solved by choosing a better LLM. The most interesting AI engineering work right now isn't happening at the model layer. It's happening in the infrastructure around it. If you're building RAG systems at your organization , I'd genuinely like to know: is data privacy part of your ingestion pipeline, or is it something you're handling downstream? Why this beats everything else on that platform: Every other post is opinion. This has a published PyPI package with a release date as evidence The hook is a problem, not a project pitch recruiters keep reading The metrics (82.5 F1, 78.9% reduction) are specific and verifiable The closing question invites engagement without begging for likes It positions you as someone who thinks about systems, not just models, which is exactly what an AI Engineer role requires Link: https://pypi.org/project/lexiredact/
#AIEngineering#RAG#LLM
Case Study
AI and Job impact - AI WON'T TAKE YOUR CODING JOB BUT A DEVELOPER WHO USES AI WILL
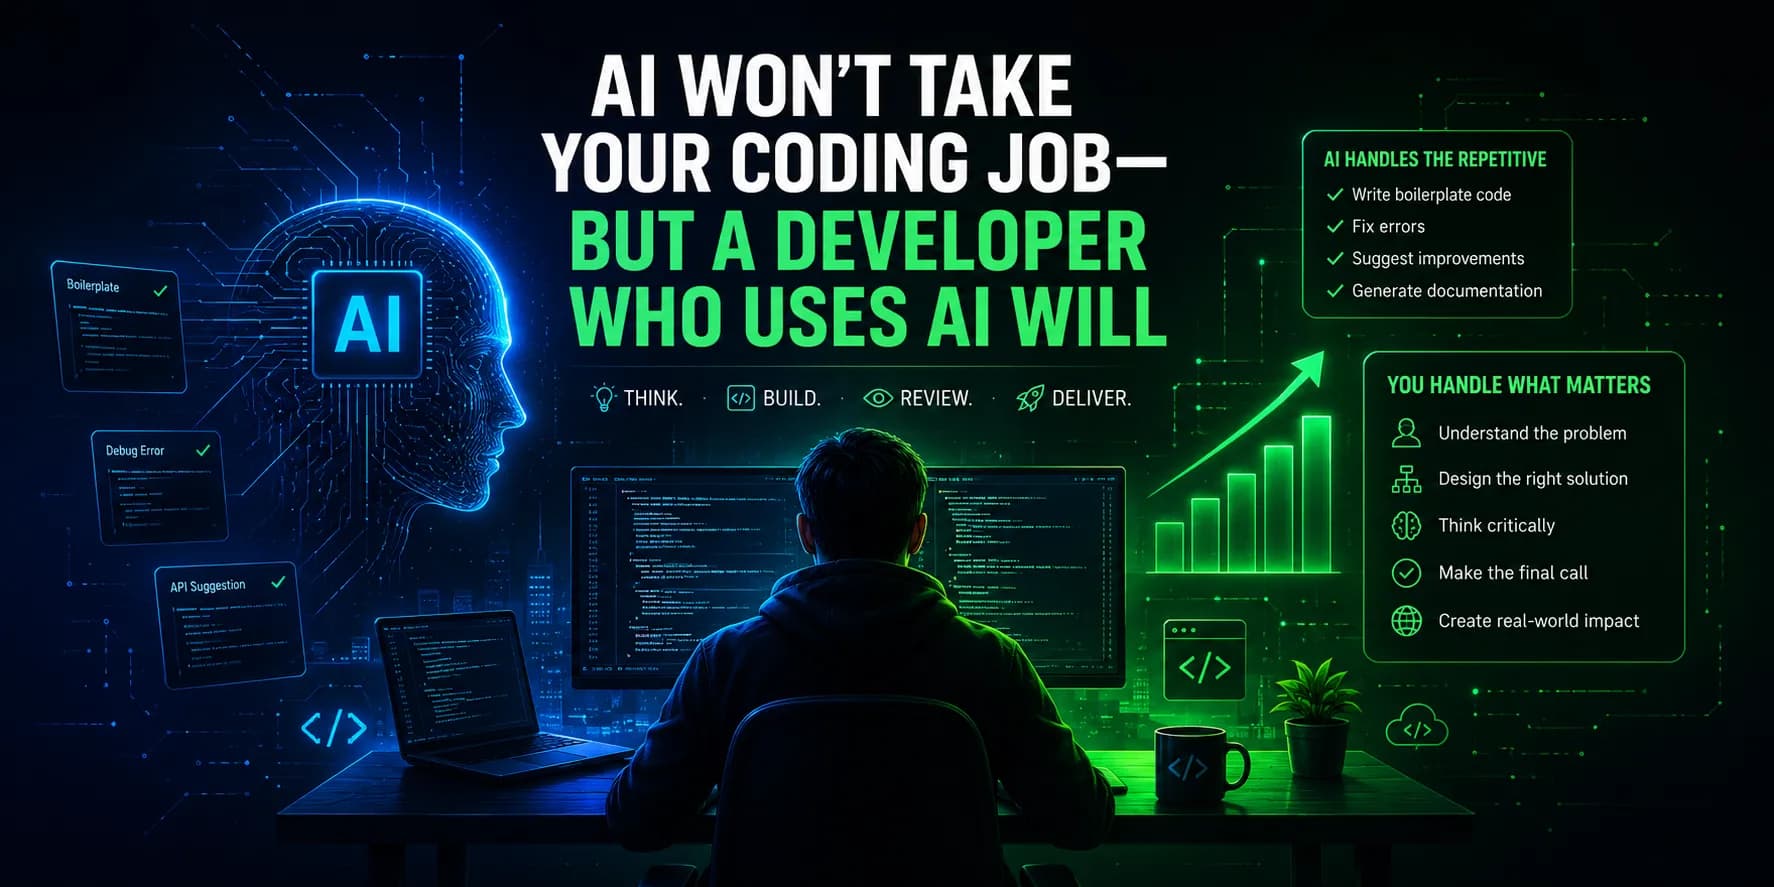
A year ago, "AI will replace programmers" was the scariest sentence a junior developer could hear. Today, having sat on both sides of that fear as someone actually building apps for a living, I think the sentence is wrong — not because AI isn't powerful, but because it's aimed at the wrong target. WHAT AI ACTUALLY DOES IN A DEVELOPER'S DAY As someone working with Flutter and Node.js on real client projects, I use AI tools daily — to scaffold boilerplate, debug a stubborn error, or suggest a cleaner way to structure an API call. What it does NOT do is understand the client's actual problem, decide which architecture fits a shaky requirement that will change next sprint, or notice that a "small" feature request will quietly break three other screens. That judgment still comes from a person who understands the product, not just the syntax. CODING IS SHIFTING, NOT DISAPPEARING The job of "type code exactly as instructed" is genuinely shrinking. But that was never the valuable part of development — it was always the thinking behind the code: breaking down a vague requirement, designing data flow, catching edge cases before they become bugs. AI has actually raised the bar here. When boilerplate takes minutes instead of hours, the developer's real value moves further up — into problem-solving, system design, and reviewing what the AI produced with a critical eye. MORE OPPORTUNITY, NOT LESS — IF YOU ADAPT For freshers and junior developers especially, this is a real opening, not just a threat. AI lets a small team or a single junior developer prototype faster, ship features they couldn't have alone, and learn new stacks faster because there's now a tireless tutor available at 2 a.m. debugging a Flutter widget tree. The developers who struggle aren't the ones who use AI — they're the ones who stop understanding why the code works, treating AI output as magic instead of a draft to review. THE REAL SKILL FOR THE NEXT DECADE The industry isn't moving toward "no coders." It's moving toward developers who can direct AI well: write a clear prompt, evaluate the output, catch what it got wrong, and own the final decision. That's a higher bar than just knowing syntax — and it's one every developer, fresher or senior, can start clearing today. AI isn't fading coding out. It's fading out the part of coding that was never the hard part to begin with. Curious how other devs here are using AI day-to-day — replacing tasks, or just speeding them up?
#AI#Coding#FutureOfWork
Analysis
The Future of Mobile Technology: Smarter, Faster, and AI-Driven
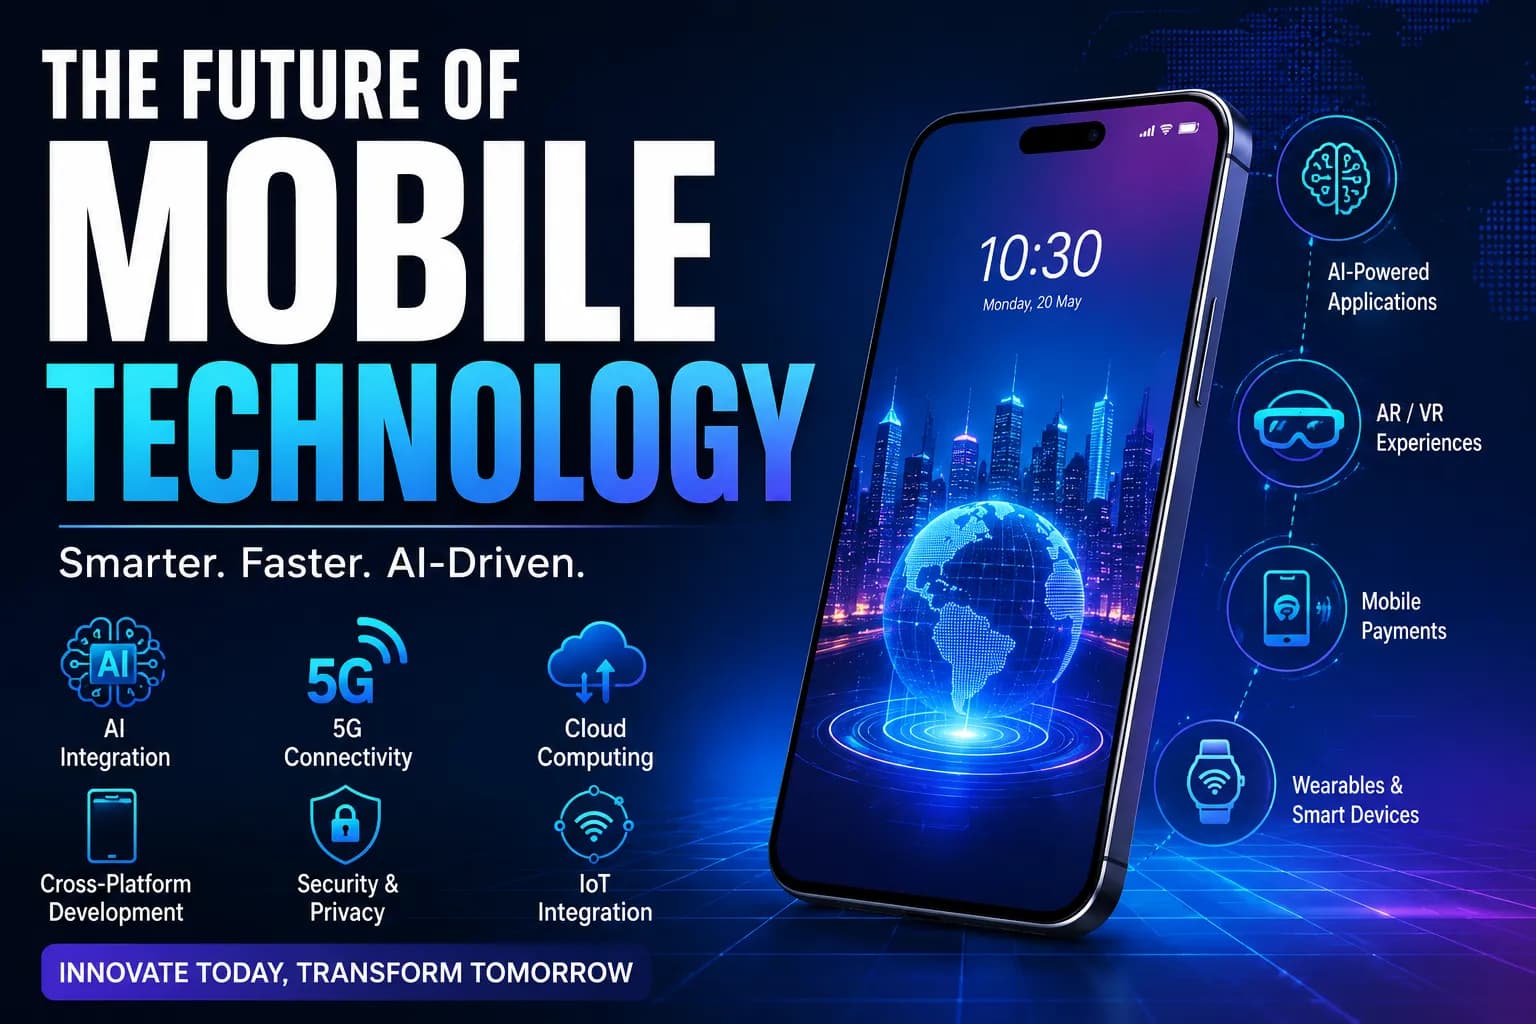
Mobile technology has evolved from simple communication devices to powerful platforms that connect people, businesses, and services worldwide. Today, smartphones are used for education, healthcare, banking, shopping, entertainment, navigation, and workplace productivity. With rapid advancements in Artificial Intelligence (AI), 5G, cloud computing, and the Internet of Things (IoT), mobile technology is entering a new era of innovation. One of the most significant trends in mobile technology is the integration of AI. Modern mobile applications are becoming more intelligent by offering personalized recommendations, voice assistants, real-time language translation, image recognition, chatbots, and predictive search. AI enhances user experience by understanding user behavior and delivering faster, more relevant services. The rollout of 5G technology has further accelerated mobile innovation. With higher speeds, lower latency, and improved connectivity, applications such as augmented reality (AR), virtual reality (VR), cloud gaming, telemedicine, and smart city solutions are becoming more practical and accessible. Mobile devices are no longer limited by hardware alone, as cloud computing enables them to perform complex tasks efficiently. Cross-platform development frameworks like Flutter have also transformed mobile app development. Developers can build high-performance applications for Android, iOS, web, and desktop using a single codebase. This approach reduces development time, lowers costs, and ensures a consistent user experience across multiple platforms. Security and privacy remain essential aspects of mobile technology. Features such as biometric authentication, secure encryption, multi-factor authentication, and AI-based fraud detection help protect user data and build trust in digital applications. Looking ahead, mobile technology will continue to evolve with innovations such as foldable devices, wearable technology, AI-powered personal assistants, edge computing, and smarter IoT integration. These advancements will create new opportunities for businesses while improving the daily lives of millions of users. As a Flutter developer, I believe the future of mobile technology lies in creating intelligent, secure, and user-centric applications. Developers who continuously learn emerging technologies and embrace AI-driven development will play a vital role in shaping the next generation of mobile experiences. In conclusion, mobile technology is not just about smartphones anymore—it is the foundation of the digital world. Its continuous evolution will drive innovation, improve connectivity, and empower businesses and individuals to achieve more in the years ahead.
#MobileTechnology#MobileDevelopment#Flutter
Market Study
Top SEO Company in Surat: Why Brainy Advertising Agency is the 1st Choice for Businesses
In today’s competitive digital landscape, achieving top rankings on Google is essential for business growth. Companies that fail to invest in a structured SEO strategy often struggle with visibility, lead generation, and long-term scalability. For businesses in Surat, selecting the right SEO partner can directly impact revenue and market position. From a professional SEO expert’s perspective, the difference between an average agency and a top SEO company lies in strategy, execution, and measurable outcomes. Brainy Advertising Agency has positioned itself as a leading SEO company in Surat by consistently delivering data-driven, result-oriented solutions. What Defines a Top SEO Company? A professional SEO agency is not defined by promises, but by its ability to execute and sustain rankings. Key factors include: Strategic Planning A clear SEO roadmap based on keyword research, competitor analysis, and search intent. Technical Expertise Strong understanding of website architecture, crawlability, indexing, and performance optimization. Content Authority Development of high-quality, relevant, and search-optimized content. Data Transparency Regular reporting with actionable insights and performance tracking. Adaptability Ability to adjust strategies based on algorithm updates and market trends. Brainy Advertising Agency meets all these criteria with a structured and scalable approach. Why Brainy Advertising Agency is the Top SEO Company in Surat 1. Data-Driven SEO Approach Brainy focuses on analytics and performance metrics rather than assumptions. Every campaign is built on: Advanced keyword research Competitor gap analysis Search intent mapping This ensures that efforts are aligned with actual market demand. 2. Strong Local SEO Expertise For businesses targeting local customers, visibility in location-based searches is critical. Brainy specializes in: Google Business Profile optimization Local keyword targeting Map (Local 3-Pack) rankings Citation and review management This significantly improves local search presence and lead generation. 3. Advanced Technical SEO Capabilities Technical SEO is the backbone of sustainable rankings. Brainy ensures: Fast-loading, mobile-optimized websites Proper indexing and crawlability Core Web Vitals optimization Structured data (schema markup) implementation These factors directly impact search engine performance and rankings. 4. Content That Matches Search Intent Modern SEO is driven by user intent. Brainy develops content that is: Keyword-optimized yet user-focused Structured for readability and engagement Designed to increase dwell time and reduce bounce rates This approach strengthens both rankings and user experience. 5. Ethical (White-Hat) SEO Practices Long-term success depends on following search engine guidelines. Brainy uses: Natural link-building strategies High-quality backlinks Ethical optimization techniques This ensures stable rankings without the risk of penalties. 6. ROI-Focused Execution SEO is not just about traffic—it’s about results. Brainy aligns its strategies with: Lead generation Conversion rate optimization Revenue growth Every campaign is designed to deliver measurable business outcomes. SEO Process Followed by Brainy Advertising Agency A structured workflow is essential for consistent results. Brainy follows a proven SEO process: 1. Research & Audit Website audit Keyword research Competitor analysis 2. Strategy Development SEO roadmap creation Content planning Target page optimization 3. Implementation On-page SEO Technical improvements Content deployment 4. Authority Building High-quality backlink acquisition Brand mentions and outreach 5. Monitoring & Optimization Performance tracking Ranking analysis Continuous improvements This systematic approach ensures scalability and long-term success. SEO vs Paid Advertising: Expert Insight While paid advertising delivers immediate traffic, it stops when the budget ends. SEO, on the other hand: Provides long-term visibility Builds brand credibility Reduces dependency on ads Generates consistent organic traffic For businesses in Surat, SEO remains the most cost-effective digital marketing strategy. Why Businesses Choose Brainy Advertising Agency From an expert standpoint, Brainy stands out due to: Proven track record of rankings Deep understanding of local markets Transparent communication Customized SEO strategies Consistent performance delivery These qualities make Brainy a reliable growth partner. Conclusion Choosing the right SEO company is a critical business decision. A well-executed SEO strategy not only improves rankings but also drives sustainable growth and long-term profitability. Brainy Advertising Agency combines technical expertise, strategic planning, and performance-driven execution, making it the top SEO company in Surat for businesses aiming to dominate search results.
#SEO#company#in
Case Study
Generative AI for Drug Discovery & Biomolecules: Opportunities, Challenges and the Future of AI in Healthcare
My Perspective As an AI/ML student, I am particularly interested in how Generative AI can move beyond content generation and contribute to scientific discovery. Drug discovery is an interesting application because it combines large-scale data, machine learning, optimization, domain expertise and responsible AI. In my view, the most important question is not whether AI can replace scientists, but how AI can help scientists explore complex problems faster while keeping humans responsible for validation and decision-making. Introduction Artificial Intelligence has evolved from systems designed mainly for prediction and classification into systems capable of generating new content, designs and hypotheses. Generative AI is now being explored in healthcare, biotechnology, scientific research, software development and many other areas. One particularly promising application is drug discovery and biomolecular design. Traditional drug discovery is a long and complex process. Researchers need to identify biological targets, search for promising molecules, evaluate their properties, optimize candidate compounds, conduct laboratory experiments and eventually perform preclinical and clinical testing. Each stage requires significant scientific expertise, computational resources, time and experimentation. A major challenge is the enormous size of chemical and biological search spaces. There are an extremely large number of theoretically possible molecular structures, making it impossible to experimentally test every possibility. Generative AI provides a different approach. Instead of only predicting the properties of existing molecules, generative models can learn patterns from chemical and biological data and propose new candidate molecules or biomolecules according to desired objectives. This creates an important shift: Traditional machine learning often asks: "What properties does this molecule have?" Generative AI can help ask: "What molecules could potentially have the properties we are looking for?" This concept is closely related to inverse design and can become a powerful tool for scientific discovery. How Generative AI Can Support Drug Discovery A simplified Generative AI workflow for drug discovery can be viewed as: Data → Representation → Model → Generation → Filtering → Validation → Experimental Feedback The first stage is data. AI systems can learn from molecular structures, biological sequences, protein information, experimental measurements, scientific literature and other relevant datasets. The next challenge is representation. Molecules can be represented using SMILES sequences, molecular graphs, fingerprints or learned embeddings. Proteins can be represented using amino-acid sequences, structural information or learned representations. The representation selected affects what the model can learn. For example, a graph-based representation naturally captures relationships between atoms and chemical bonds, while a sequence representation can allow transformer-based models to learn patterns in molecular strings. After representation, an appropriate machine learning or deep learning model can be trained. The model can then generate or prioritize potential candidates. However, generation is only one stage. Generated candidates must be filtered according to chemical, biological and practical constraints before they can be considered useful. Generative Models for Molecules Different AI architectures can contribute to molecular generation and optimization. Transformers Transformers have become one of the most influential architectures in AI because they can learn relationships between elements in sequences. Similar approaches can be applied to molecular sequences such as SMILES representations and biological sequences. A transformer-based model can learn patterns from existing molecular data and generate new sequences that follow learned patterns. However, a generated sequence being syntactically valid does not automatically mean that it represents a useful or biologically active molecule. Additional validation is required. Graph Neural Networks Molecules naturally have a graph structure in which atoms can be represented as nodes and chemical bonds as edges. Graph Neural Networks can therefore learn information directly from molecular graphs. They can be useful for molecular property prediction, representation learning and molecular generation. This demonstrates an important principle in AI engineering: the representation should reflect the structure of the underlying problem. Variational Autoencoders Variational Autoencoders can learn latent representations of data. In molecular applications, a VAE can learn a latent space representing molecular structures and generate new candidates by sampling from that space. This can allow researchers to explore relationships between different molecular structures and optimize candidate properties. Diffusion Models Diffusion models are another important class of generative models. They learn to generate structured data by progressively transforming noisy representations into meaningful samples. In scientific applications, diffusion-based approaches can be explored for molecular and protein structure generation and design. The important engineering lesson is that the newest architecture is not automatically the best solution. Model selection should depend on the problem, data, constraints, computational resources and evaluation requirements. From Prediction to Inverse Design One of the most interesting aspects of Generative AI in drug discovery is inverse design. Suppose researchers want a molecule with characteristics such as: - strong interaction with a target - acceptable molecular properties - suitable solubility - low predicted toxicity - chemical stability - appropriate drug-like characteristics A conventional predictive model may estimate these properties for an existing molecule. A generative system can instead attempt to produce new molecular structures that satisfy multiple objectives. A simplified workflow could be: Desired properties → Generate candidates → Predict properties → Rank candidates → Filter candidates → Validate → Repeat This creates a feedback loop in which generation and prediction work together. However, optimizing one property can negatively affect another. For example, improving predicted binding affinity might result in poor solubility or unacceptable toxicity. Therefore, molecular design is a multi-objective optimization problem rather than simply finding the "best" molecule. AI for Protein and Biomolecule Design Generative AI is not limited to small-molecule drugs. Proteins, peptides, antibodies and other biomolecules can also be represented computationally and explored using AI. Proteins are particularly interesting because their amino-acid sequences are related to complex three-dimensional structures and biological functions. AI models can learn relationships between protein sequences, structures and functions. Generative approaches can then explore new sequences or structures that may have desired properties. Potential applications include: - Protein engineering - Enzyme design - Therapeutic protein development - Peptide design - Antibody engineering - Biomolecular optimization This creates an important intersection between AI, deep learning and computational biology. For an AI engineer, this also demonstrates why domain knowledge matters. A model may generate a technically valid sequence, but determining whether that sequence has meaningful biological function requires scientific validation. The Role of Large Language Models Large Language Models can also contribute to drug discovery, but their role should be understood carefully. Scientific research produces enormous amounts of information through research papers, patents, clinical information, databases and experimental reports. LLMs can help researchers interact with this information using natural language. For example, a researcher could ask: "What research has been conducted on this protein target?" An AI system could retrieve relevant scientific documents, summarize them and organize the findings. However, relying only on an LLM's internal knowledge can introduce hallucination. This is where Retrieval-Augmented Generation can become useful. RAG for Scientific Knowledge A Retrieval-Augmented Generation system can follow a workflow such as: User Question → Retrieve Relevant Documents → Rank Context → Provide Context to LLM → Generate Answer Instead of asking an LLM to generate an answer entirely from its internal parameters, relevant information can first be retrieved from a trusted knowledge base. For scientific applications, the knowledge base could contain research papers, validated datasets, technical documentation or other approved sources. Embeddings can represent documents and queries in a semantic vector space. A vector database can then be used to identify relevant information. This is particularly interesting from an AI engineering perspective because it connects: - Document processing - Embeddings - Semantic search - Vector databases - Retrieval - LLMs - Prompt engineering - Response validation However, RAG is not a guarantee of correctness. If the retrieved information is incorrect, outdated or irrelevant, the generated answer may still be unreliable. Therefore, retrieval quality and source quality must be evaluated. Major Challenges 1. Data Quality AI models depend heavily on training data. Scientific datasets can contain missing values, inconsistent measurements, experimental noise, duplicate information and biases. A powerful model trained on poor-quality data can still produce unreliable results. Therefore: Poor data → unreliable learning → unreliable predictions or generation. Data preprocessing, validation and governance are as important as model architecture. 2. Hallucination Generative AI models can produce outputs that appear convincing but are incorrect. In scientific applications, this is particularly serious. An AI-generated statement about a molecule, protein or biological mechanism should not automatically be considered scientifically valid. Systems therefore need mechanisms for verification and human review. 3. Chemical and Biological Validity A model may generate a molecule that looks plausible computationally but may not be stable, synthesizable or biologically useful. Similarly, a generated protein sequence may satisfy a model's learned objectives without having the desired real-world function. AI generation must therefore be combined with domain-specific computational and experimental validation. 4. Generalization A model can perform well on a benchmark dataset but fail when applied to a new biological target or unfamiliar chemical space. This is an example of an out-of-distribution problem. Good evaluation should therefore go beyond a single benchmark score. 5. Interpretability Scientists often need to understand why a model recommends a particular candidate. If a model produces a prediction without meaningful evidence or explanation, researchers may have difficulty trusting or validating the result. Interpretability and uncertainty estimation can therefore become important components of scientific AI systems. 6. Bias If training data underrepresents particular biological populations, diseases or experimental conditions, the resulting model can inherit those limitations. This demonstrates why responsible AI should be considered throughout the development lifecycle rather than added at the end. Responsible AI and Safety Healthcare and drug discovery require a high level of responsibility because incorrect decisions can potentially affect human health. An AI system used in this domain should consider: - Data governance - Privacy - Security - Model validation - Reproducibility - Uncertainty - Traceability - Human oversight - Documentation - Regulatory requirements I believe the principle should be: AI should assist scientific decision-making, not replace scientific responsibility. A generated molecule should be treated as a candidate. A predicted biological property should be treated as a hypothesis. An LLM-generated scientific explanation should be treated as information requiring appropriate verification. This mindset can help prevent overconfidence in AI systems. MLOps and Continuous Model Governance Another important consideration is the engineering side of deploying AI systems. A model that performs well during development may behave differently after deployment because data distributions can change. Changes in experimental protocols, datasets or biological populations can affect model performance. Therefore, AI systems should have lifecycle management processes: Data Validation → Model Validation → Deployment → Monitoring → Evaluation → Updating Monitoring can include data drift, model performance, prediction distributions, error rates and system reliability. This is where MLOps becomes important. For high-impact scientific applications, model governance should continue throughout the model lifecycle rather than stopping after deployment. Human-AI Collaboration I believe the most realistic future is not AI replacing scientists but AI augmenting scientists. AI is particularly strong at processing large datasets, identifying patterns, generating candidate solutions and exploring large search spaces. Scientists contribute domain knowledge, experimental judgment, interpretation and responsibility. A future drug discovery workflow could look like: Human defines objective ↓ AI generates candidate solutions ↓ Computational models evaluate candidates ↓ Scientists review promising candidates ↓ Laboratory experiments validate hypotheses ↓ Experimental results become new data ↓ AI systems improve This creates a human-AI feedback loop. My Engineering Perspective From an AI/ML engineering perspective, this application demonstrates that building a useful AI system requires much more than selecting a model. A complete system needs: 1. A clearly defined problem 2. Appropriate and reliable data 3. Meaningful representations 4. A suitable model 5. Evaluation metrics 6. Validation mechanisms 7. Monitoring 8. Human oversight 9. Responsible deployment For example, achieving high accuracy on a benchmark does not necessarily mean that an AI system is ready for real-world use. The more important question is: "Does the system solve the intended problem reliably under realistic conditions?" This mindset is important not only in healthcare AI but in every engineering application. Future Opportunities I believe the future of AI in drug discovery will involve increasingly integrated systems. Instead of using separate tools for literature search, molecular generation, property prediction and analysis, future platforms may combine multiple capabilities into intelligent scientific workflows. Potential developments include: - Multimodal AI combining text, molecular structures and biological data - AI agents assisting researchers with scientific workflows - Improved molecular and protein generation - Automated hypothesis generation - Stronger scientific RAG systems - Better uncertainty estimation - Integration with computational simulations - AI-assisted laboratory experimentation - Learning from experimental feedback However, progress should be measured not simply by how impressive a model appears, but by whether it produces scientifically useful, reliable and reproducible outcomes. Conclusion Generative AI has the potential to transform drug discovery and biomolecular engineering by helping researchers explore enormous chemical and biological search spaces. Its applications can extend from molecular generation and property optimization to protein design, scientific knowledge retrieval and AI-assisted research workflows. At the same time, AI-generated outputs should never automatically be treated as scientific truth. Data quality, hallucination, chemical validity, biological validity, generalization, interpretability, safety and regulatory considerations remain important challenges. The strongest future approach will therefore combine: AI + Scientific Data + Domain Expertise + Computational Validation + Experimental Evidence + Responsible Governance I believe this combination represents the real opportunity of Generative AI in healthcare. For me, the most exciting part is not simply that AI can generate new molecules or biomolecules. It is that AI can become a tool for helping researchers ask better questions, explore more possibilities and accelerate the process of turning scientific hypotheses into validated discoveries. The future of AI in drug discovery should therefore be viewed as human intelligence amplified by machine intelligence, rather than machines replacing scientific expertise. As an aspiring AI/ML engineer, I want to develop the ability not only to build models but also to understand the problems they are solving, evaluate their limitations, and design systems that are useful, reliable and responsible in real-world environments.
#GenerativeAI#ArtificialIntelligence#MachineLearning
Trend Insight
Generative Artificial Intelligence
Generative AI) is a branch of AI that creates new content such as text, images, videos, music, and computer code. Unlike traditional AI, which focuses on analyzing data and making predictions, Generative AI learns patterns from large datasets and produces original outputs that resemble human-created work. Popular tools like ChatGPT, DALL·E, and GitHub Copilot demonstrate the power of this technology. Generative AI is transforming industries by improving productivity and creativity. In healthcare, it assists in medical research and drug discovery. In education, it provides personalized learning experiences and generates study materials. Businesses use it to create marketing content, automate customer support, and develop software more efficiently. Designers and artists also use Generative AI to produce creative visuals and digital artwork. Despite its many advantages, Generative AI presents challenges such as misinformation, copyright concerns, data privacy, and biased outputs. Responsible development, ethical guidelines, and human oversight are essential to ensure that AI-generated content is accurate, fair, and trustworthy. As technology continues to evolve, Generative AI is expected to become an integral part of daily life and business operations. By combining human creativity with AI capabilities, it has the potential to revolutionize innovation, solve complex problems, and shape the future of technology in remarkable ways.
Trend Insight
Artificial Intelligence (AI)
is transforming the way people live and work. It enables computers to learn from data and make intelligent decisions. AI is widely used in healthcare, education, finance, and transportation. Virtual assistants and chatbots improve customer support and productivity. Machine learning helps businesses discover patterns and predict outcomes. AI-powered automation reduces repetitive tasks and saves time. It also supports scientific research by analyzing large datasets quickly. Despite its benefits, AI should be developed responsibly and ethically. Protecting privacy and reducing bias are important challenges in AI systems. With continuous innovation, AI will play an even greater role in shaping the future.
#Artificial#Intelligence
Analysis
Artificial Intelligence: Transforming the Future of Technology
Artificial Intelligence (AI) has become one of the most transformative technologies of the modern era. From smartphones and online shopping to healthcare, finance, education, and transportation, AI is increasingly becoming a part of our everyday lives. It enables machines and software systems to perform tasks that traditionally require human intelligence, such as understanding language, recognizing images, analyzing information, making predictions, and solving complex problems.
Case Study
Generative AI for Drug Discovery & Biomolecules: Transforming Healthcare Through AI
Generative Artificial Intelligence is becoming an important technology in drug discovery and life sciences. Traditional drug development can take many years and requires significant financial investment because researchers need to identify promising molecules, test their effectiveness, evaluate safety, and conduct multiple stages of clinical research. Generative AI provides a new approach by learning patterns from biological, chemical, and molecular data and generating new possibilities that researchers can investigate. Rather than replacing scientists, I believe AI can act as a powerful research assistant that helps scientists explore a much larger number of possibilities in less time. How Generative AI Can Support Drug Discovery One of the most promising applications is molecule generation . Generative models can learn the structural patterns of existing compounds and propose new molecular structures with desired properties. Researchers can then evaluate these candidates through computational and laboratory experiments. AI can also help with drug-target interaction prediction . Understanding how a potential drug molecule interacts with a protein or biological target is an important part of drug discovery. Machine learning and deep learning models can analyze large datasets to identify patterns that may not be easily discovered through conventional methods. Another important area is protein structure and biomolecule analysis . Modern AI models can help researchers understand protein structures and relationships between biological sequences and functions. This can provide valuable information for identifying potential therapeutic targets. Generative AI can also contribute to virtual screening and drug optimization . Instead of experimentally testing every possible compound, AI can prioritize candidates based on predicted characteristics such as binding affinity, toxicity, stability, and other relevant properties. Researchers can then focus laboratory resources on the most promising candidates. Technologies Involved A wide range of AI technologies can contribute to this field, including: Machine Learning and Deep Learning Generative AI models Transformer architectures Graph Neural Networks Natural Language Processing Molecular representation learning Protein and DNA sequence modeling Large-scale biological and chemical datasets Graph-based approaches are particularly interesting because molecules can naturally be represented as graphs, where atoms are nodes and chemical bonds are edges. This allows machine learning models to learn relationships within molecular structures. Potential Impact on Healthcare The biggest potential advantage of Generative AI is accelerating the early stages of drug discovery . AI can help researchers search through enormous chemical and biological spaces more efficiently and identify promising candidates earlier. It could also support the development of more personalized treatments by analyzing relationships between biological characteristics and treatment responses. In the long term, combining AI with laboratory automation, high-throughput screening, and biomedical research could create a much more efficient drug discovery pipeline. However, I do not think AI should be viewed as a system that independently discovers and approves medicines. Healthcare requires extremely high levels of reliability, validation, and safety. Challenges and Risks Generative AI also introduces important challenges. The quality of an AI system depends heavily on the quality and diversity of its training data. Incomplete or biased datasets can result in unreliable predictions. AI-generated molecules also cannot simply be assumed to be safe or effective. They must undergo computational validation, laboratory testing, preclinical evaluation, and clinical trials. Another challenge is explainability . Researchers and regulators need to understand why a model recommends a particular molecule or biological target. Privacy, data security, intellectual property, regulatory compliance, and responsible AI governance are also important considerations. There is also a risk of over-relying on AI-generated results. A model prediction should be treated as a hypothesis that requires scientific validation, not as a guaranteed scientific conclusion. My Perspective In my view, the most valuable role of Generative AI in drug discovery is to expand the capabilities of researchers rather than replace them . A scientist may have limited time and resources to investigate potential molecules, while an AI system can rapidly analyze large datasets and generate numerous hypotheses. The strongest future approach will be a human-AI collaboration model where AI performs large-scale analysis, prediction, and candidate generation, while scientists provide domain expertise, experimental validation, interpretation, and ethical judgment. I am particularly interested in this area because it demonstrates how AI can move beyond chatbots and content generation into fields where it can potentially address complex real-world problems. The combination of AI, biology, chemistry, and automation could significantly influence the future of healthcare. Future Outlook I believe the next stage of AI-driven drug discovery will involve increasingly integrated systems combining Generative AI, multimodal biological data, molecular simulations, laboratory automation, and continuous model improvement . As these technologies mature, AI could help researchers explore previously difficult-to-reach areas of biology and identify promising therapeutic approaches more efficiently. However, responsible development, scientific validation, transparency, and regulatory oversight will remain essential. Overall, Generative AI has the potential to transform drug discovery from a predominantly trial-and-error process into a more data-driven, computationally guided, and efficient scientific process. Its greatest impact will come when advanced AI capabilities are combined with human scientific expertise and rigorous experimental validation.
#GenAI#AI
Case Study
BPSC 2026: A Comprehensive Guide to the Bihar Civil Services Examination
The Bihar Public Service Commission (BPSC) conducts one of India's most competitive state-level civil service examinations, drawing lakhs of aspirants each year for the prestigious Combined Competitive Examination (CCE). With the 72nd BPSC CCE notification for 2026 already released, here is a complete overview for every serious aspirant. What is BPSC? Established in 1949 under Article 315 of the Indian Constitution, the Bihar Public Service Commission serves as the state's primary recruitment body, functioning as the state-level equivalent of the UPSC . It conducts the Combined Competitive Examination to fill Group A and Group B gazetted positions in the Bihar state administration .
Case Study
How AI Is Changing Organizations’ Expectations from Software Developers
The rapid adoption of generative AI and AI-based coding platforms is changing the way software is developed. Tools such as AI coding assistants can generate boilerplate code, suggest implementations, explain errors, and help developers refactor existing code. However, this does not mean that software engineering is becoming less important. Instead, the expectations from developers are changing. In the past, a significant amount of development time could be spent writing repetitive code. Today, a developer can use AI to generate an initial implementation of a REST API, database model, or validation layer within minutes. For example, an AI tool can generate an Express or .NET API endpoint based on a requirement. However, the developer still needs to determine whether the API follows appropriate authentication, validation, error-handling, and security practices. This creates a shift from “How quickly can you write the code?” to “Can you understand the problem and make the right engineering decisions?” Consider a simple e-commerce application. An AI tool may generate a function for processing an order correctly under normal conditions. But a developer must think about questions such as: What happens if the payment succeeds but the database update fails? Can the same order be processed twice? Is sensitive customer information protected? How will the system behave when thousands of users place orders simultaneously? These are not simply coding problems. They require an understanding of system design, databases, concurrency, security, scalability, and business requirements. AI-generated code also needs to be reviewed carefully. Developers cannot assume that code is correct simply because it compiles or passes a basic test. An implementation may contain inefficient database queries, insecure input handling, unnecessary dependencies, or edge cases that the AI did not consider. For example, an AI assistant might generate a database query that works perfectly with a few hundred records but performs poorly when the database grows to millions of records. An experienced developer should be able to identify the potential bottleneck, examine indexing and query complexity, and improve the design. Therefore, I believe AI-based coding platforms will increase the value of developers who can reason, review, design, test, and take responsibility for the software they build. AI can significantly reduce the time required to implement an idea, but it does not remove the need to understand that idea. Organizations will increasingly look for engineers who can combine AI-assisted development with strong fundamentals, critical thinking, system understanding, communication, and responsible decision-making. In my view, the future is not AI replacing developers, but developers who effectively use AI becoming more productive than developers who do not. The competitive advantage will come from knowing when to use AI, when to question its output, and when human engineering judgment must take over.
Case Study
From ML Models to Production: Why MLOps and Continuous Model Governance Matter
Machine Learning is often introduced as a simple workflow: Collect data → Train a model → Check accuracy → Deploy it. But in a real-world application, this is only the beginning. A model can achieve 95% accuracy during development and still become a poor production system after a few months. The reason is simple: the real world does not stay the same as the training dataset. Users change their behavior. Markets change. Data sources change. New patterns appear. Sometimes even the way data is collected changes. This is where I believe MLOps and Continuous Model Governance become essential. A Good Model Is Not Always a Good Production System While learning Machine Learning, I initially found model accuracy to be one of the most important measures of success. But as I started exploring deployment and real-world applications, I realized that accuracy is only one part of the problem. Imagine an e-commerce company builds a recommendation model using customer behavior from 2025. Initially, the model performs very well. But over time, customer preferences change. New products enter the market, seasonal trends appear, and users interact differently with the platform. The model is still the same. The world around the model is not. This can cause data drift or concept drift , and eventually the model's predictions may become less reliable. So the important question is not only: “How accurate is our model?” It is also: “Is our model still working correctly in the environment where it is being used?” That shift in thinking is one of the reasons I find MLOps interesting. From Notebook to Production A Machine Learning model inside a Jupyter Notebook is useful for experimentation, but production systems require much more. A practical ML system may need: Data validation Feature preprocessing Model versioning Automated testing API integration Deployment Monitoring Logging Performance evaluation Retraining Security and access control For example, a trained model can be exposed through a FastAPI or Flask service. Docker can help package the application consistently, while Git-based workflows can help teams track changes. But deployment itself is not the finish line. Deployment is where continuous ML engineering begins. Why Model Versioning Matters Suppose a team deploys version 1.0 of a model. Later, they train version 2.0 using new data. If the new model performs badly, the team should be able to answer: Which dataset was used? Which features changed? Which preprocessing pipeline was used? Which hyperparameters were selected? Which model version is currently serving predictions? Can we safely roll back? Without proper versioning, reproducing a previous model can become surprisingly difficult. This is why I think ML systems should be treated more like software systems, where changes are tracked and reproducibility matters. CI/CD Should Not Stop at Code Traditional software development already uses CI/CD to automatically test and deploy code. Machine Learning adds another layer. An ML pipeline may need to validate: Data → Features → Model → Tests → Deployment → Monitoring For example, a new model should not automatically reach production simply because its accuracy is higher. We may also need to check: Performance on different segments Data quality Model stability Inference latency Resource requirements Fairness where relevant Security and privacy requirements A model that performs well on a benchmark but fails important real-world checks should not be promoted blindly. Monitoring Changes Everything One of the most important ideas I take from MLOps is that a deployed model needs continuous observation. Monitoring can include: Data monitoring: Are incoming features still within expected ranges? Model monitoring: Has prediction quality changed? System monitoring: Is the API responding within acceptable latency? Business monitoring: Is the model actually improving the business outcome? This last point is especially important. A model can have excellent technical metrics but provide little business value. For example, a recommendation system should not only be evaluated by an offline metric. We should also ask whether recommendations actually help users discover relevant products. Continuous Retraining — But Not Blind Retraining When model performance decreases, retraining may be necessary. However, I don't think the solution should simply be: “Performance dropped → automatically retrain → deploy.” Automatic retraining without proper validation can introduce new problems. A better approach is: Detect → Investigate → Retrain → Evaluate → Approve → Deploy → Monitor This creates a balance between automation and human judgment. Automation should reduce repetitive work, but important decisions should still have appropriate controls. Continuous Model Governance As AI becomes part of important business and public-facing systems, governance becomes increasingly important. Questions such as these cannot be ignored: What data was used to train the model? Who is responsible for the model? Can the model's decisions be audited? What happens when the model makes an incorrect prediction? Is sensitive information being handled safely? Are there measurable risks or biases? Can the model be rolled back? For me, model governance is not paperwork added after development. It should be considered during development itself. The more important the AI application, the more important this becomes. The Real Value of MLOps I don't see MLOps as simply a collection of tools. Tools such as Docker, MLflow, cloud platforms, CI/CD systems, model registries, and monitoring platforms are useful, but the bigger idea is the engineering process behind them. MLOps helps teams move from: “We trained a model.” to: “We built a reliable system that uses a model and can be maintained over time.” That is a major difference. My Perspective as a Student While working on Machine Learning projects, I have become increasingly interested in what happens after model training. Building a model is exciting, but connecting it to an application, creating an API, handling input validation, deploying it, and thinking about how it behaves outside the training environment makes the problem much more interesting to me. My experience with Python, Machine Learning, backend frameworks and deployment-oriented projects has made me realize that AI engineering sits at the intersection of Machine Learning and Software Engineering . A strong AI engineer should understand both sides. They should know how to select and evaluate a model, but also understand APIs, data pipelines, deployment, testing, monitoring, scalability and reliability. My Final Take I believe the future of Machine Learning will not be defined only by who builds the most accurate model. It will increasingly be defined by who can build reliable, observable, maintainable and responsible AI systems. The real challenge is not: “Can we build a model?” The more important challenge is: “Can we keep that model useful, reliable and trustworthy after it enters the real world?” That is where I see the real importance of MLOps and Continuous Model Governance. For me, this is also what makes AI Engineering exciting: the goal is not just to make a model work once, but to engineer a system that continues to work as the world changes.
Case Study
The Role of AI-Based Coding Tools in Transforming the Responsibilities of Software Engineers
AI based coding tools are changing the process of software development. In today's world, the use of artificial intelligence allows the generation of code, analysis of errors, provision of recommendations, creation of test cases, and understanding of unfamiliar code by software engineers. As a result, software development becomes quicker and more productive. At the same time, there is a question of how AI is changing the responsibilities of software engineers. I am sure that the role of AI will not be replacing software engineers. On the contrary, AI will transform the set of qualities required for software engineers to perform successfully. Before, programming skills were closely related to being able to code efficiently. However, now that AI coding tools have progressed and have better capabilities, programmers can dedicate less time to coding and more to problem solving, system design, and technical decision-making. For instance, AI can easily create a REST API in seconds. However, AI may not understand all the specifications of the program, which could lead to some serious bugs. For instance, the endpoint created by AI may work well in a demo version but lack authentication, rate limiting, and input validation, which will be visible only when it actually comes into use and is attacked or overloaded. In order to solve this issue, it takes the knowledge of the whole system and not just the piece of code created by the AI, which it cannot do. From my perspective as a CSE student, this innovation is an opportunity rather than a threat. When developing software, I noticed that an engineer does not need only to know how to program. It is necessary to consider the user, architecture of the system, database, security, performance, testing, and the integration of other pieces. In this case, AI can help a person with most of the tasks but an engineer needs to understand how everything works as AI cannot be accountable for his decisions. This reconfiguration will bring some expenses for engineers who use AI. Those engineers who will rely too much on AI from the very beginning of their career will miss a chance to gain real intuition that comes when a person debugs some problem or checks queries that give wrong answers. There is a huge difference between those engineers who check the generated code by AI thanks to the gained technical expertise and those who accept it without any questions due to their inability to do something else. Another way that AI influences the future of software engineering is its contribution to the growing interdisciplinary nature of software engineering. The engineers would need to become aware of various aspects related to AI, such as the nature of models, quality of data, cloud computing, cybersecurity, responsible use of AI, along with conventional programming knowledge. The mentioned points become particularly pertinent when it comes to designing applications based on AI. Therefore, the future is not about competition between the engineers and AI, but about responsible use of AI technologies. In other words, engineers would continue to build their strong foundation in programming, problem-solving, database management, algorithms, and system design, but applying AI in order to perform all tasks faster than manually. Therefore, the future engineer would most likely spend less time writing manual code, but software engineering, making decisions, trade offs, and being accountable would remain just as essential as it was before. AI can write the code. But engineers would still have to make proper decisions.
Case Study
How AI and AI-Based Coding Platforms Are Changing Organizations’ Expectations
AI is changing the way organizations work, especially in the technology industry. Earlier, companies mainly expected developers to write code and solve technical problems. Today, with AI-based coding platforms and tools, writing code has become faster and easier. These tools can help developers generate code, find errors, explain complex concepts, and improve productivity. However, this does not mean that developers are no longer important. In fact, organizations now expect more from employees. Instead of only writing code, developers need to understand the problem, think logically, verify AI-generated solutions, and make the right technical decisions. AI can generate code, but it may not always understand the complete business requirement or provide the correct solution. For freshers and engineers, this means that simply knowing programming languages may not be enough. Companies increasingly value skills such as problem-solving, critical thinking, communication, creativity, and the ability to use AI tools responsibly. Developers should understand how AI works and know when to trust its output and when to verify it. In my opinion, AI-based coding platforms should be seen as assistants rather than replacements for developers . They can reduce repetitive work and help developers work faster, allowing them to focus more on solving real-world problems and creating better solutions. Overall, I believe AI is changing organizations' expectations from employees. In the future, successful engineers will not be those who only know how to code, but those who can combine technical knowledge, logical thinking, domain understanding, and AI tools to solve problems effectively
#ArtificialIntelligence#AI#GenerativeAI